You see Googlebot in your server logs. Google Search Console shows the page as crawled. But the page never appears in search results. This is one of the most frustrating SEO problems because crawling looks like progress — yet indexing never happens. The reasons vary from quality signals to technical blocks. This guide explains why Google crawls but does not index, how to diagnose each cause, and what to fix first.
Crawling vs indexing: what the difference means
Crawling is the process of discovering and downloading a page. Indexing is the process of analyzing, storing and making that page available in search results. A page can be crawled without being indexed. This is not a bug — it is Google deciding that the page is not worth adding to the index.
In Google Search Console, this often appears as "Crawled — currently not indexed" or "Discovered — currently not indexed". Both mean Google knows about the page but has chosen not to index it. Understanding why requires looking at quality, duplication, technical signals and site-level trust.
The key point: crawling is not a promise of indexing. Many SEO specialists assume that if Googlebot visited, the page will be indexed. That assumption is wrong and leads to wasted effort.
Reason 1: thin or low-quality content
The most common reason is content quality. Google may decide that the page does not provide enough unique value to justify indexing. Signs of thin content:
— very short pages with little text;
— pages that repeat content from other pages on the same site;
— auto-generated content without added value;
— pages that are mostly ads or affiliate links;
— pages with no clear purpose or user intent.
If the page is thin, the fix is not technical. You need to add real value: more depth, unique data, examples, images, or remove the page entirely. Google is increasingly selective about what it indexes, especially on new or low-authority sites.
Reason 2: duplicate or near-duplicate content
If a page duplicates content from another page, Google may index one version and skip the other. Duplication can be internal or external.
Internal duplication:
— same content on multiple URLs;
— pagination without canonical;
— parameter URLs that serve the same content;
— www and non-www versions both accessible.
External duplication:
— content copied from another site;
— syndicated content without canonical to the original;
— product descriptions copied from a manufacturer.
To diagnose, check canonical tags, compare URLs, and use Google cache checker to see which version Google has stored. If the page is a duplicate, either consolidate it with the main version or make it unique.
Reason 3: technical blocks that survive crawling
Sometimes a page is crawled but blocked from indexing by a technical signal. Common cases:
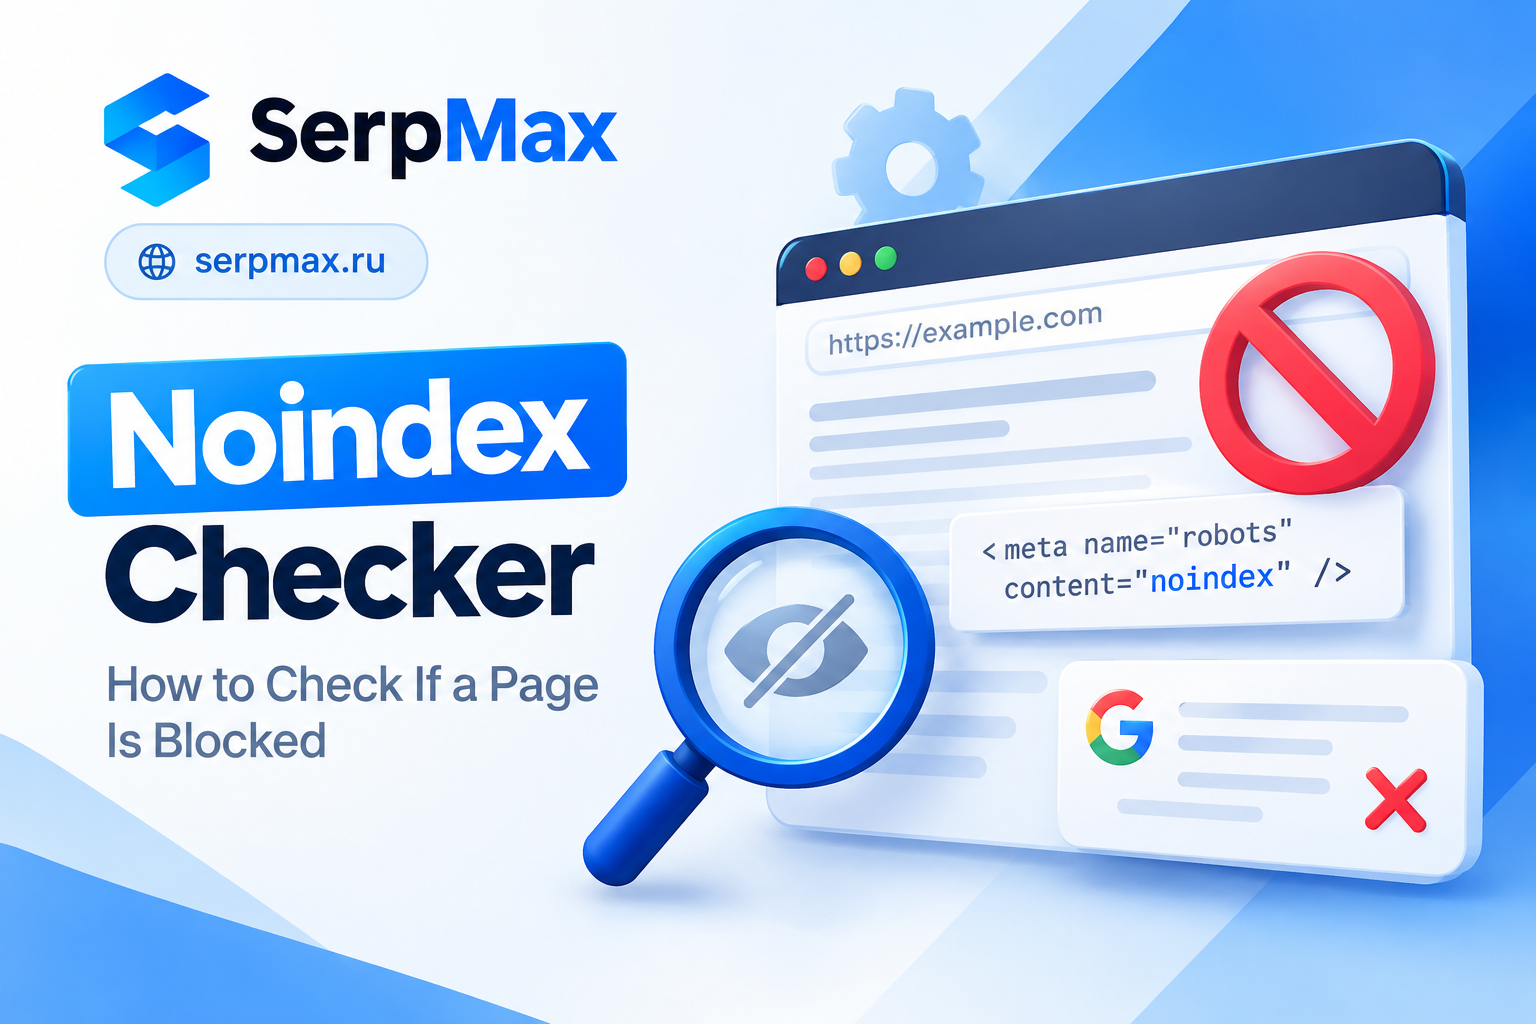
— noindex in meta robots;
— noindex in X-Robots-Tag header;
— canonical pointing to a different page;
— robots.txt blocking resources needed for rendering;
— JavaScript content not rendered properly.
These signals can be invisible if you only check the HTML. For example, a CDN may add X-Robots-Tag: noindex without your knowledge. Or a canonical tag may point to a page you did not intend.
What to check:
— meta robots on the page;
— X-Robots-Tag in HTTP headers;
— canonical tag;
— robots.txt for blocked resources;
— rendered HTML in Search Console URL Inspection.
Reason 4: site-level quality and trust
Google evaluates not only individual pages but the whole site. If the site has low trust, new pages may be crawled but not indexed. Factors that affect site-level trust:
— overall content quality;
— backlink profile;
— user engagement signals;
— history of penalties or manual actions;
— technical health of the site.
On a new domain, this is especially common. Google may crawl new pages but wait to see whether the site proves useful before indexing. In this case, the fix is not a single page — it is building the site overall: more quality content, better internal linking, earning links, improving technical health.
Reason 5: crawl budget and prioritization
Google allocates a crawl budget to each site. If the site has many URLs, Google may crawl some pages but not index them because it prioritizes other pages. This is common on large sites with many low-value pages.
Signs of crawl budget issues:
— many pages discovered but not crawled;
— important pages crawled less often than low-value pages;
— server response times slow;
— many redirects, 404s or soft 404s.
To improve:
— fix server response times;
— remove or noindex low-value pages;
— improve internal linking to important pages;
— keep sitemaps clean and up to date.
How to diagnose the exact reason
A practical diagnostic sequence:
— check Search Console URL Inspection for the page;
— look at the "Coverage" or "Page indexing" report;
— check meta robots and X-Robots-Tag;
— check canonical tag;
— check rendered HTML in URL Inspection;
— compare content with other pages on the site;
— check for external duplication;
— check site-level issues in Search Console.
If the page is technically fine but still not indexed, the issue is likely content quality or site-level trust. In that case, technical fixes will not help — you need to improve the content or build the site overall.
For a broader check of indexing signals, SEO audit can help verify noindex, canonical, redirects and other factors in one place.
What to fix first
Priority order:
— remove accidental noindex or X-Robots-Tag;
— fix canonical if it points to the wrong page;
— improve content quality if the page is thin;
— consolidate duplicates;
— fix technical issues that affect rendering;
— improve internal linking;
— request re-crawl after fixes.
Do not request re-crawl before fixing the underlying issue. If the page is thin or duplicated, re-crawling will not help — Google will simply decide again not to index it.
FAQ
Why does Google crawl but not index my page?
Most often because the content is thin, duplicated, or the page has a technical block like noindex or a wrong canonical. On new sites, site-level trust can also be a factor.
How long does it take for Google to index a crawled page?
It varies. Some pages are indexed within days, others take weeks or never get indexed. It depends on content quality, site authority and crawl budget.
Does requesting indexing help?
It can speed up the process, but only if the underlying issue is fixed. If the content is thin or duplicated, requesting indexing will not help.
What does "Crawled — currently not indexed" mean?
It means Googlebot visited the page but decided not to add it to the index. The reason is usually content quality, duplication or site-level trust.
Can noindex survive crawling?
Yes. Googlebot can crawl a page and see noindex, then choose not to index it. Check both meta robots and X-Robots-Tag.
What if the page is unique but still not indexed?
Check site-level trust, internal linking and crawl budget. On new sites, Google may wait before indexing new pages.
How do I check if a page is indexed?
Use site: search, Google Search Console URL Inspection, or a Google cache checker. If the page does not appear, it is not indexed.
Does page speed affect indexing?
Indirectly. Slow pages may be crawled less often, which can delay indexing. Improving speed helps crawl efficiency.
Can I force Google to index a page?
No. You can request indexing, but Google decides. Focus on fixing the underlying issues instead of forcing.
How do I know which issue is blocking indexing?
Start with Search Console URL Inspection, check technical signals, then evaluate content quality and site-level trust. The exact reason is not always stated, but the diagnosis usually narrows it down.